If you want to spider/index a site to discover all the links on it you can use the Web crawler tool.
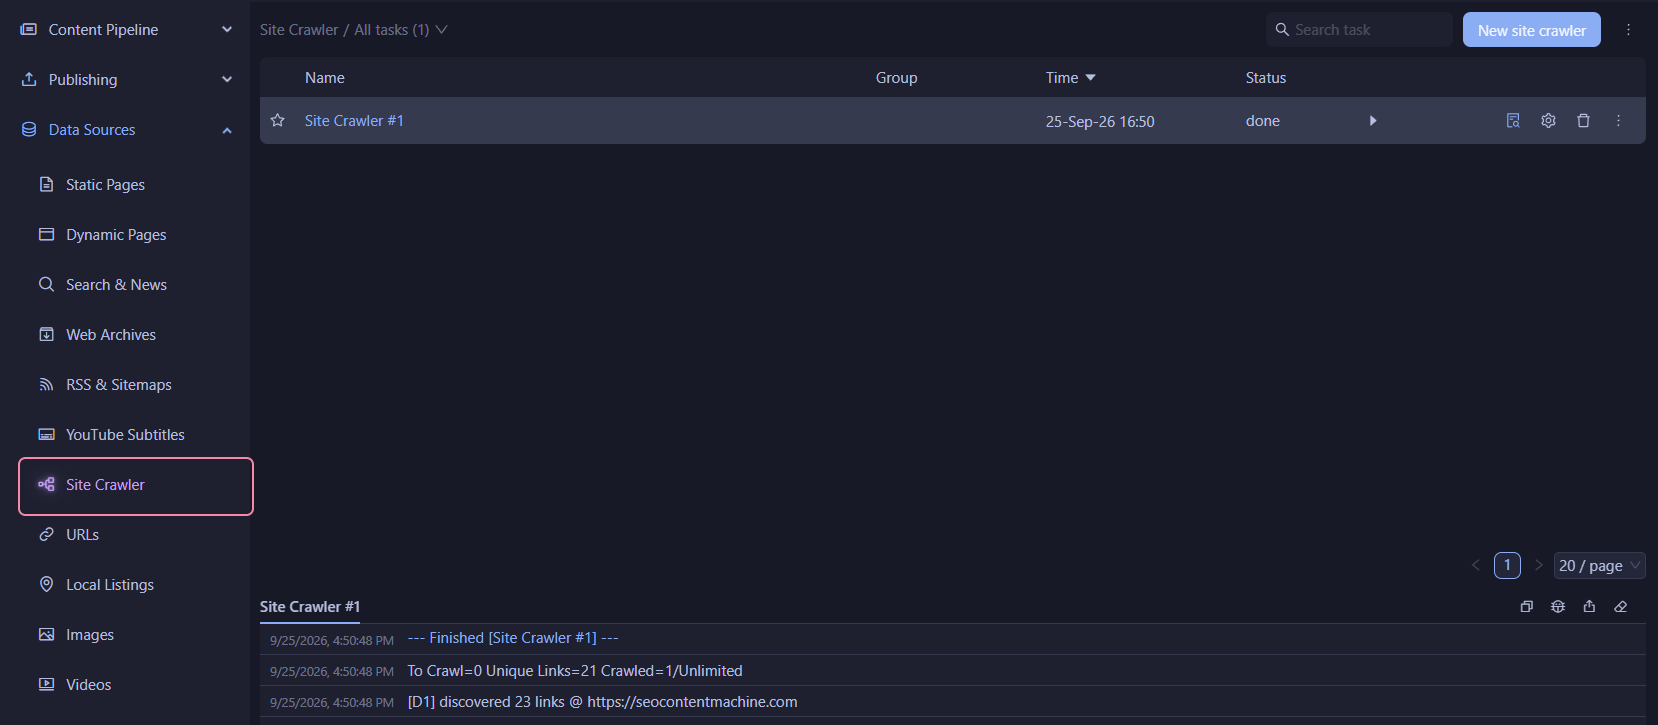
How does the web crawler tool work?
Provide a starting link (or links). The tool will then download each page to discover links.
The tool is now called ‘Site Crawler’. It is under ‘Data Sources’.
Put your links in ‘Crawl domain’, 1 per line.
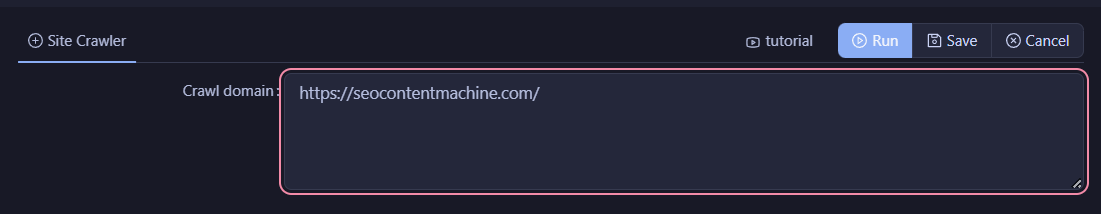
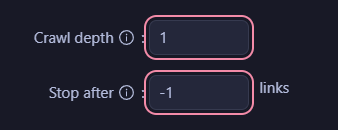
The crawl depth is set to 1, so it will only find links on the pages you give it.
Set it to > 1, ie 2 or 3, to make the crawler follow extra links down.
You can make the crawler exit early after it reaches a set number of links.
Default -1, means it will go forever .
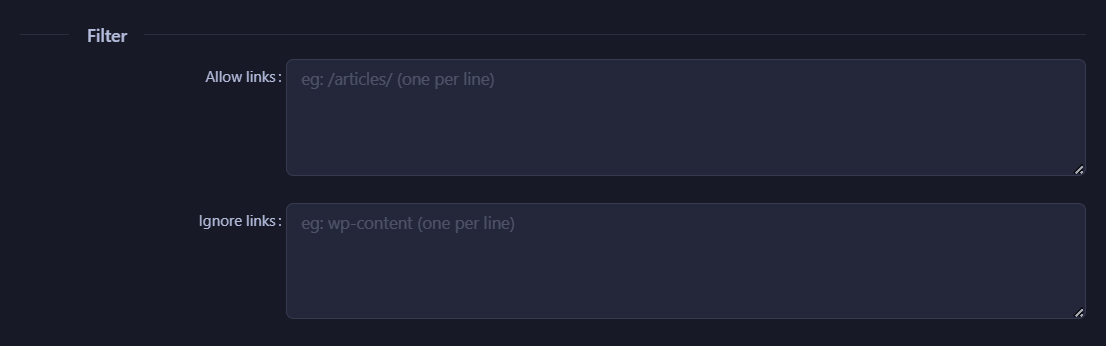
There is some filtering to keep or remove links.
Results are saved to your hard drive.
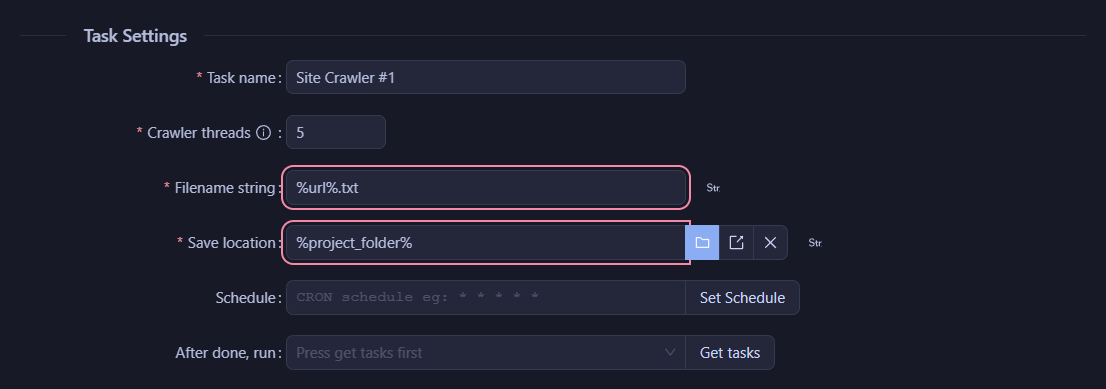
Press ‘Run’.

The log shows how many links it found.
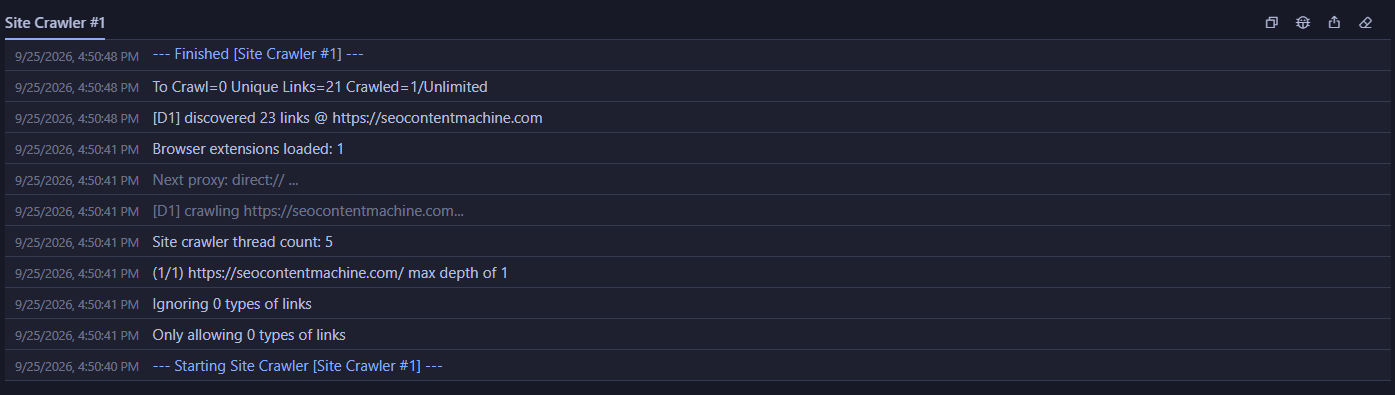
Output will be in 2 files.
- Internal links
- External links
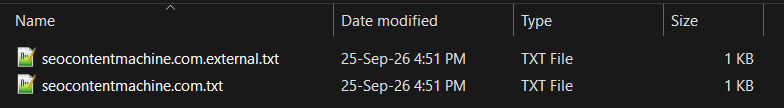
ie seocontentmachine.com.txt has the internal links. seocontentmachine.com.external.txt has the external links.
The urls you provide will use the domain to treat it as ‘internal’
How to increase crawling speed
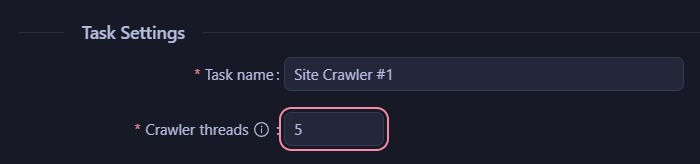
You can increase or decrease the number of threads.
It is on the task form, under ‘Task Settings’.
‘Crawler threads’. Default is 5.
Link crawler FAQ
How do I crawl a website for links?
Open ‘Site Crawler’, put the site in ‘Crawl domain’ and press ‘Run’. You get 1 file of internal links and 1 file of external links.
What is a link crawler?
It loads a page, saves every link on it, then follows those links to find more. ‘Site Crawler’ does this and saves the links to text files.
How do I crawl a whole website, not just 1 page?
Set ‘Crawl depth’ to 2 or 3 so it follows links down. Leave ‘Stop after’ at -1 for no limit, or set eg 500 to exit early.
How do I crawl only some links?
Put a path in ‘Allow links’, eg /blog/. Put what to skip in ‘Ignore links’, eg wp-content.
How do I spider a website?
Spider and crawl mean the same thing here. Use ‘Site Crawler’ the same way.